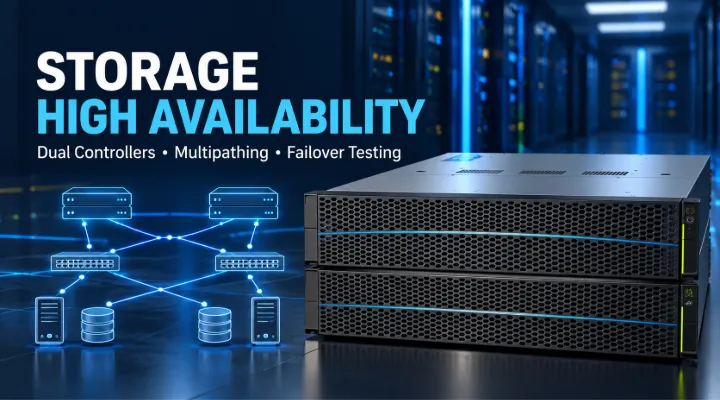
A dual-controller storage system provides building blocks for availability, but a business service depends on more than the array. Servers, switches, power, host software and operating procedures all influence whether an application keeps working during a fault. The Huawei OceanStor Dorado 2020 configuration described in the supplied ICTECH Distribution notes uses dual active-active controllers, making it a useful starting point for a shared storage availability design.
The practical question is how that design behaves when something changes or fails. A specification can describe redundant components without proving that the host paths are configured correctly or that an application can tolerate a transition. This guide explains how to evaluate the dual-controller configuration, identify remaining dependencies and define acceptance tests that connect the hardware architecture to business service requirements.
Understand the scope of dual active-active controllers
Active-active terminology indicates that both controllers participate in the supported storage operation rather than treating one as an unused spare. The exact handling of requests, ownership and paths depends on the platform implementation and configuration. Do not infer that every workload automatically divides evenly between controllers or that every host connection has the same characteristics. Ask for the supported architecture and host guidance for the selected system release.
The supplied configuration specifies 64 GB of dual-controller cache. That describes a controller resource in the quoted system, not additional usable SSD capacity. Review controller health, cache behaviour and the supported response to component faults through the system documentation and configuration review. Understanding these roles helps distinguish a controller problem from a host path problem when investigating application symptoms.
Trace the complete service dependency
Start with an application and follow its access to storage. Identify the server, host adapter or network interface, cable, switch, target port, controller and storage resource. Repeat the exercise for the alternative path. Mark every place where the routes depend on the same physical component, power source or administrative configuration. This reveals whether the proposed redundancy addresses the failures the organisation actually needs to tolerate.
Also identify dependencies outside the data path. Authentication, name services, management access and application clustering may affect the ability to continue or restore service. Not every dependency belongs in the storage quotation, but someone must own it. A shared architecture diagram helps teams agree where the storage design ends and which additional measures are required for the complete service.
Configure the host to use supported paths
Multiple physical connections are useful only when the host treats them correctly. A supported multipathing configuration allows the operating system to manage alternative paths to the same storage resource. Confirm the required software, drivers, firmware and settings for each host type. UltraPath appears in the supplied software notes, but host deployment and configuration still need an explicit owner and a validated procedure.
Check that every intended path is visible and healthy before moving production data. Record the normal path state and supported path selection policy. If one host differs from the others, understand why instead of assuming that a working connection is sufficient. Consistent configuration makes later maintenance and troubleshooting easier, particularly when the environment contains several operating systems or virtualisation platforms.
Remove avoidable switching dependencies
A single switch can remain a shared dependency even when two controllers and several host connections are present. Review the intended fabric or Ethernet design and how each host reaches the array through it. For a redundant topology, identify the components that can fail independently and the conditions under which access should continue. Use the vendor-supported connection design rather than improvising links based only on available ports.
Keep the physical and logical diagrams aligned. Two connections routed through different labels can still share a patch panel, power source or misconfigured logical service. Document device locations, switch ports and cable identifiers. Clear records help an engineer remove the intended connection during a controlled test and reduce the chance that routine work affects both sides of a supposedly redundant arrangement.
Review power and environmental readiness
The supplied notes describe redundant power supplies. To make use of that redundancy, examine how they connect to the site's power infrastructure. Two cords plugged into one vulnerable distribution point do not provide the same failure separation as an appropriately designed independent arrangement. Confirm electrical compatibility, rack distribution, cooling and access with the facilities team before installation.
Environmental readiness also includes airflow, clearances and maintenance access. A storage system can be logically redundant while remaining exposed to a shared cooling or room-level incident. Define the scope of the availability design honestly. If site loss must be addressed, it requires an additional architecture discussion rather than an assumption that controller redundancy also protects against every facility failure.
Design maintenance around supported procedures
The supplied product notes refer to non-disruptive upgrade capabilities and their prerequisites. Treat those prerequisites as part of the design. Supported hardware, software, host multipathing and a healthy starting state can all matter to a maintenance procedure. Confirm the exact upgrade path and required checks for the installed release before scheduling a change. A feature description is not approval to skip a maintenance review.
Record expected behaviour and escalation steps in the change plan. Make sure relevant teams are available to observe hosts, applications and storage during the window. Avoid promising that users will never notice any effect unless that claim is supported for the actual environment. The useful outcome is a tested and documented procedure with clear conditions, not a broad label attached to every future change.
Define measurable service acceptance
Before testing, agree what success means for the business. An application might require uninterrupted transactions, automatic reconnection within an agreed period or a controlled restart. Different services can have different expectations. Record workload levels, baseline performance and the monitoring used to observe the test. This prevents technical teams from declaring success based on a storage indicator while the application owner sees an unresolved service problem.
Choose test cases that correspond to the design's intended failure tolerance. These may include a supported path removal, switch-path interruption or controller-related procedure, performed according to the relevant guidance. Protect production data and obtain the normal operational authorisation for the test window. The purpose is to verify the planned behaviour safely, not to discover resilience by creating uncontrolled faults.
Observe failover and recovery separately
During a controlled test, record the moment the component or path becomes unavailable, the host response and the application result. Check alerts and identify which team receives them. A service can remain accessible while operating with reduced redundancy, so continued access alone does not mean the incident needs no attention. Operators must recognise the degraded condition and know how to restore the intended protection.
After the component returns, verify that paths and system health recover correctly. Record whether manual intervention is required and whether performance returns to the expected baseline. Restoration deserves its own acceptance step because an apparently successful failover can leave the system using fewer paths than intended. Update the operating instructions with what was observed, including any configuration corrections made during the exercise.
Keep recovery protection alongside availability
Availability and recoverability solve different problems. Dual controllers can contribute to continued access during certain component incidents, while snapshots and backups help address unwanted changes or loss of the primary environment. A highly available system can still serve corrupted or mistakenly deleted data. The business needs a plan for selecting and restoring an earlier usable state as well as a plan for maintaining access.
If HyperCDP is included, confirm its licence and configuration separately from the controller design. Define independent backup requirements and test restoration with the application owners. The complete service plan should explain which protection mechanism applies to each relevant incident. This avoids treating successful hardware failover as evidence that the organisation is prepared for every kind of data loss.
Maintain the design after handover
Availability can deteriorate through ordinary changes. A host rebuild may omit a multipathing setting, a switch replacement may lose a configuration detail or a cable move may combine previously separate paths. Keep an inventory and review material changes against the accepted design. Monitor path health and component alerts so a failed redundant element does not remain unnoticed until a second incident occurs.
Ask ICTECH Distribution to include the final configuration, support contacts and service coverage in the handover. The supplied notes mention three-year warranty support; verify the scope and response arrangements for the actual location and purchase. Preserve test results and maintenance prerequisites with the operational records. This gives the team a practical basis for keeping the original availability design effective as the environment grows.
Frequently asked questions
Does dual active-active mean every application is always available?
No universal guarantee follows from the controller architecture. Host paths, switching, power, application behaviour and supported configuration all influence the service outcome.
Is multipathing still needed with two controllers?
Use the supported host multipathing design for the selected platform and operating systems. Multiple cables alone do not establish correct failover behaviour.
Can redundant power supplies share one power source?
They may be physically connected that way, but the shared source remains a dependency. Review power separation against the availability requirement with the facilities team.
Are all upgrades automatically non-disruptive?
No. Verify the supported upgrade path, prerequisites and actual host environment for each maintenance operation. Test and document the expected service behaviour.
Does successful failover remove the need for backups?
No. Failover addresses defined availability scenarios. Backups and earlier recovery states address other risks, including unwanted data changes and loss of the primary environment.
Product details and enquiries
Huawei OceanStor Dorado 2020 storage system | LIC-D2020-CDP-S HyperCDP licence | D2020-SAS3.84T-CF enterprise SSD
Contact ICTECH Distribution with your capacity, host connectivity, compatibility and recovery requirements for a configuration-specific enquiry.
Configuration reference: supplied ICTECH Distribution product information and bill-of-material notes. Exact inclusions are subject to the final quotation and compatibility review.
